DexTacWAM: Touch-Aware World Models for Dexterous Manipulation
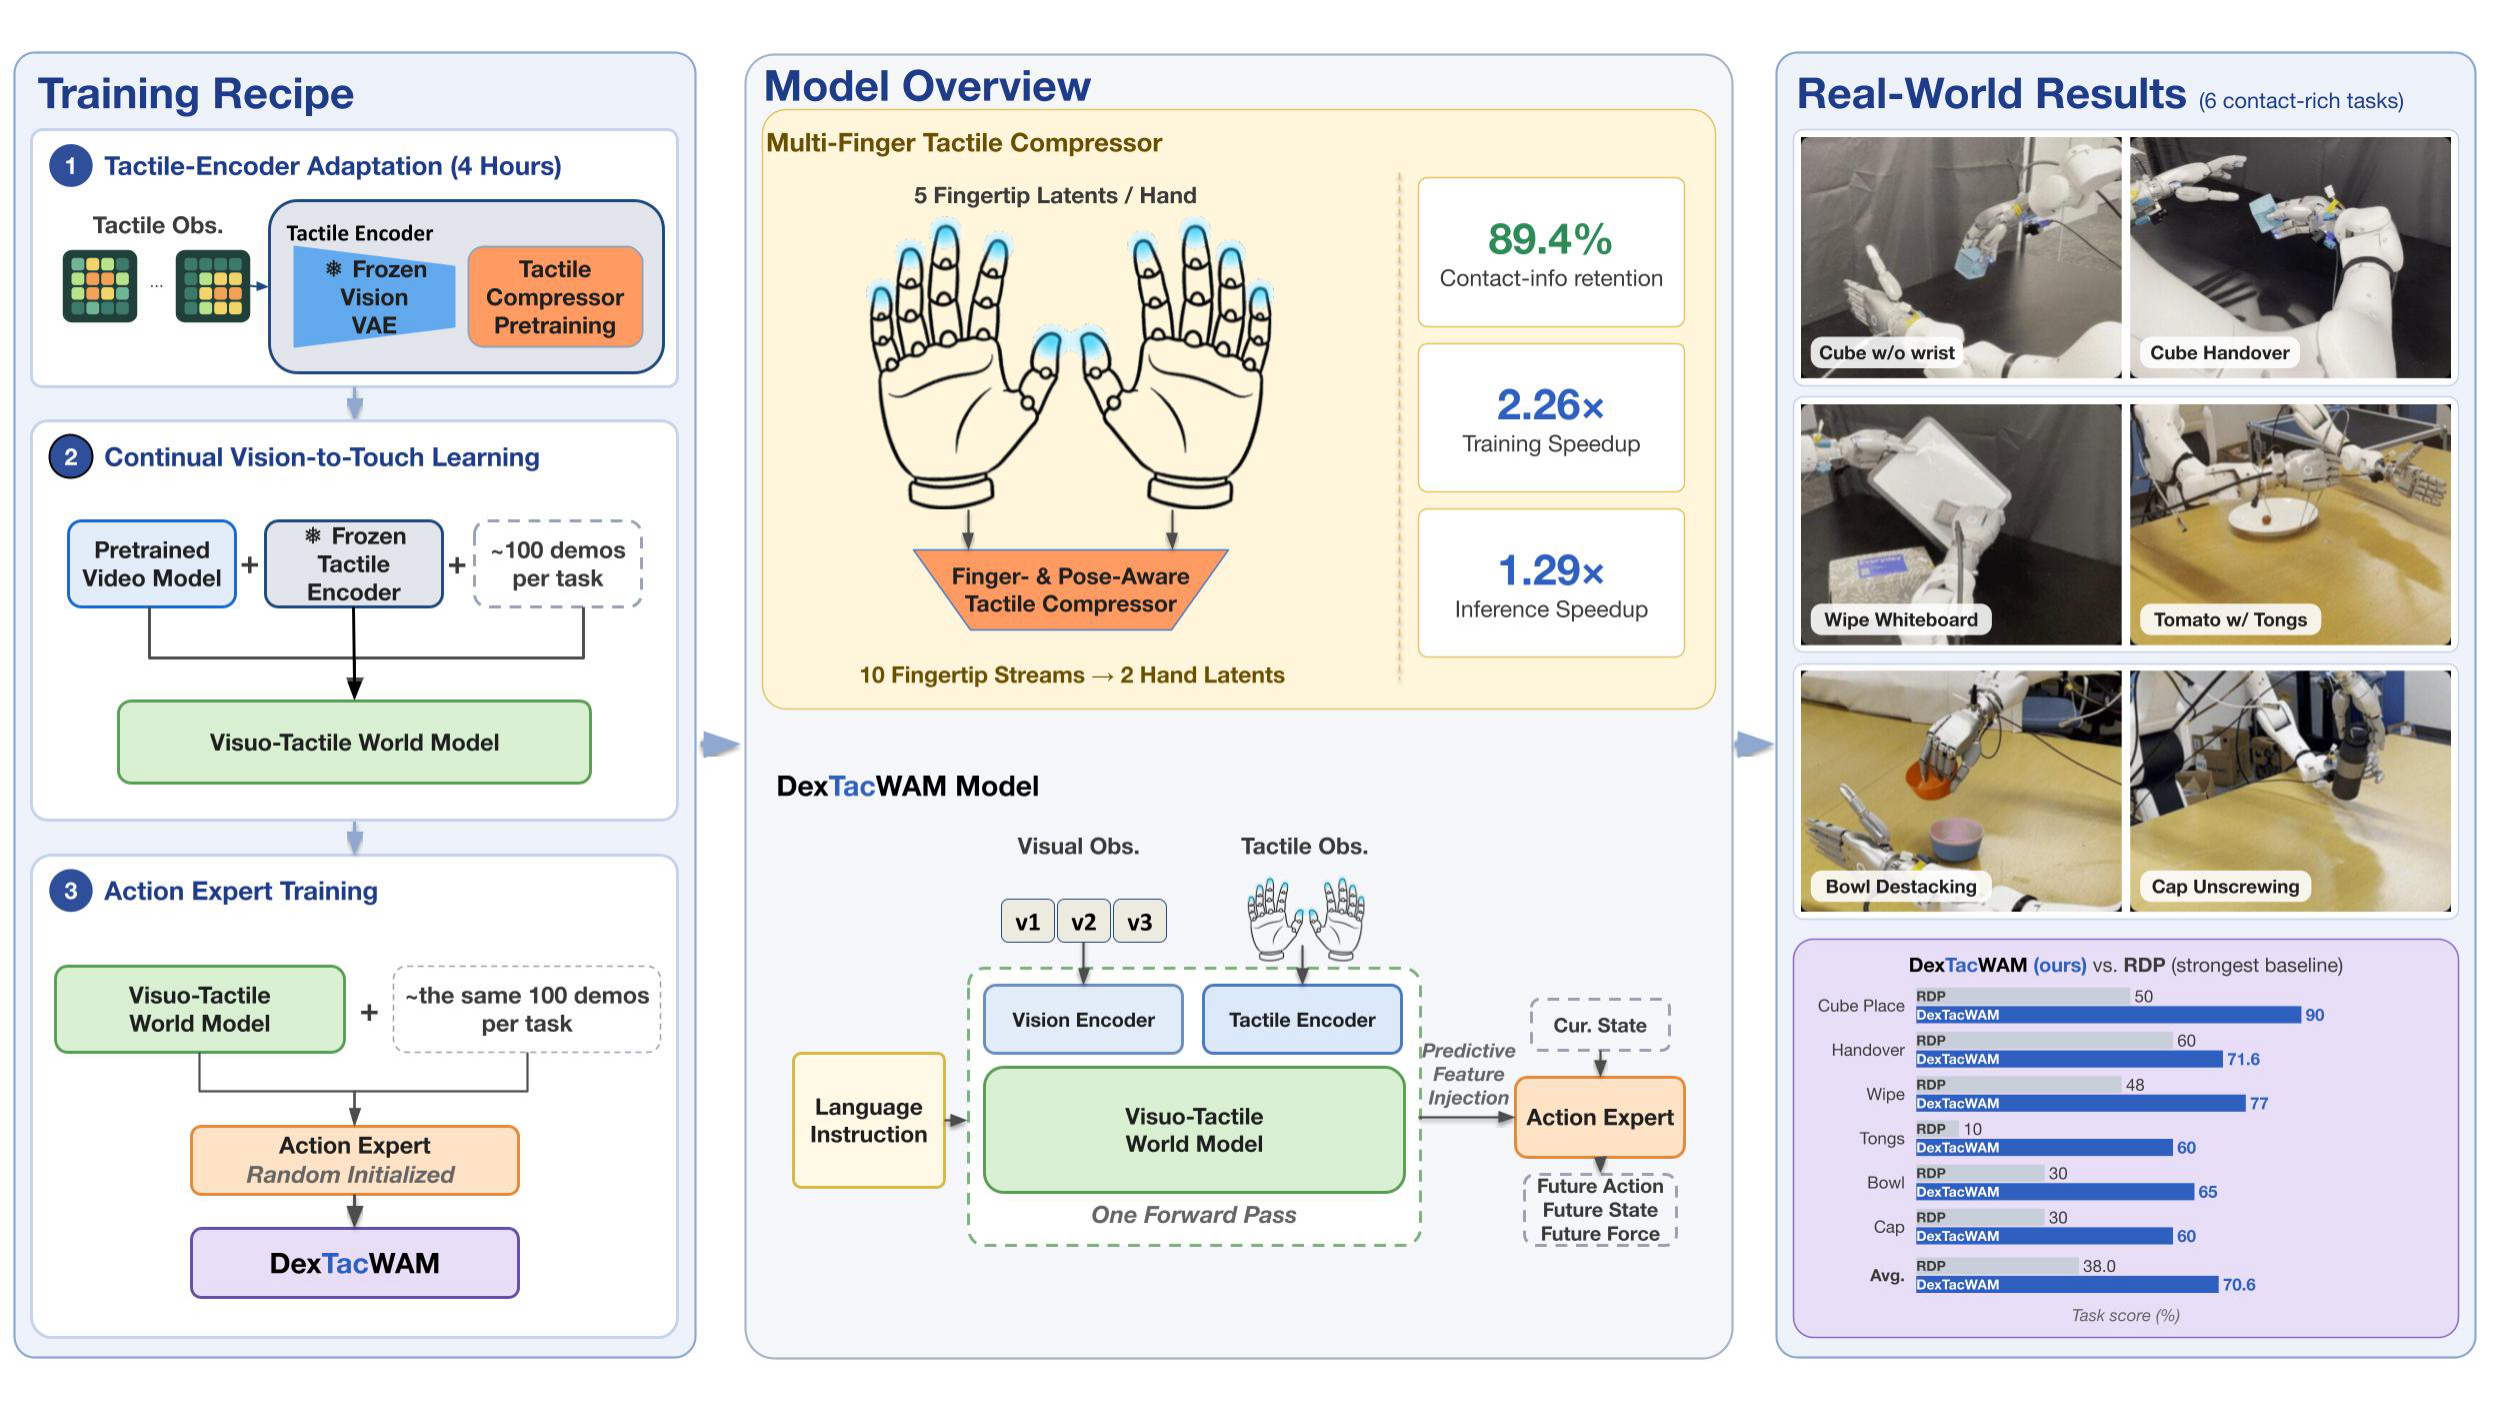
UIUC, UC Berkeley and Northwestern teach a video world model to predict touch as well as sight. On six contact-rich tasks with a Dexmate Vega and tactile fingertips, it averaged 70.6 against 38.0 for the strongest baseline.
DexTacWAM: A Visuo-Tactile World-Action Model for Dexterous Manipulation
- 1University of Illinois Urbana-Champaign
- 2University of California, Berkeley
- 3Northwestern University
* Work done during a visit to UC Berkeley · ‡ Project lead · † Equal advising, co-corresponding authors
arXiv preprint arXiv:2609.24976
Abstract
Dexterous manipulation depends on contact dynamics that are often only partially observable from vision. Recent World-Action Models (WAMs) couple predictive video world modeling with action generation, but remain largely vision-centric and therefore cannot directly model these contact dynamics. We present DexTacWAM, a visuo-tactile WAM that encodes each fingertip independently, aggregates the resulting features through a finger- and pose-aware tactile compressor, and injects the tactile latent into a video diffusion world model for joint visuo-tactile world modeling. Across six contact-rich dexterous manipulation tasks on a 22-DoF bimanual platform, DexTacWAM achieves the highest score on every task, averaging 70.6 versus 38.0 for the strongest baseline. Ablations attribute the gain to modeling contact evolution as part of the predicted world state rather than tactile conditioning alone: removing tactile world modeling reduces the four-task mean from 74.7 to 26.6 while keeping the same tactile features and action expert. After four hours of tactile-encoder adaptation with a frozen pretrained vision VAE, our continual vision-to-touch learning extends the pretrained video model to touch using roughly 100 demonstrations per task without tactile midtraining, while retaining visual prediction quality within 0.5 dB of vision-only counterparts. The compressor retains 89.4% of pre-fusion contact recall while enabling 2.26x faster training and 1.29x faster inference. Together, these results show that pretrained video priors can be extended to distributed multi-finger contact dynamics in a data- and compute-efficient manner.
Citation
@article{dextacwam2026, title = {DexTacWAM: A Visuo-Tactile World-Action Model for Dexterous Manipulation}, author = {Yuan, Haoran and Wang, Zekai and Shao, Boning and Lu, Haoran and Darrell, Trevor and Lourentzou, Ismini and Zhan, Wei}, journal = {arXiv preprint arXiv:2609.24976}, year = {2026}}Platform
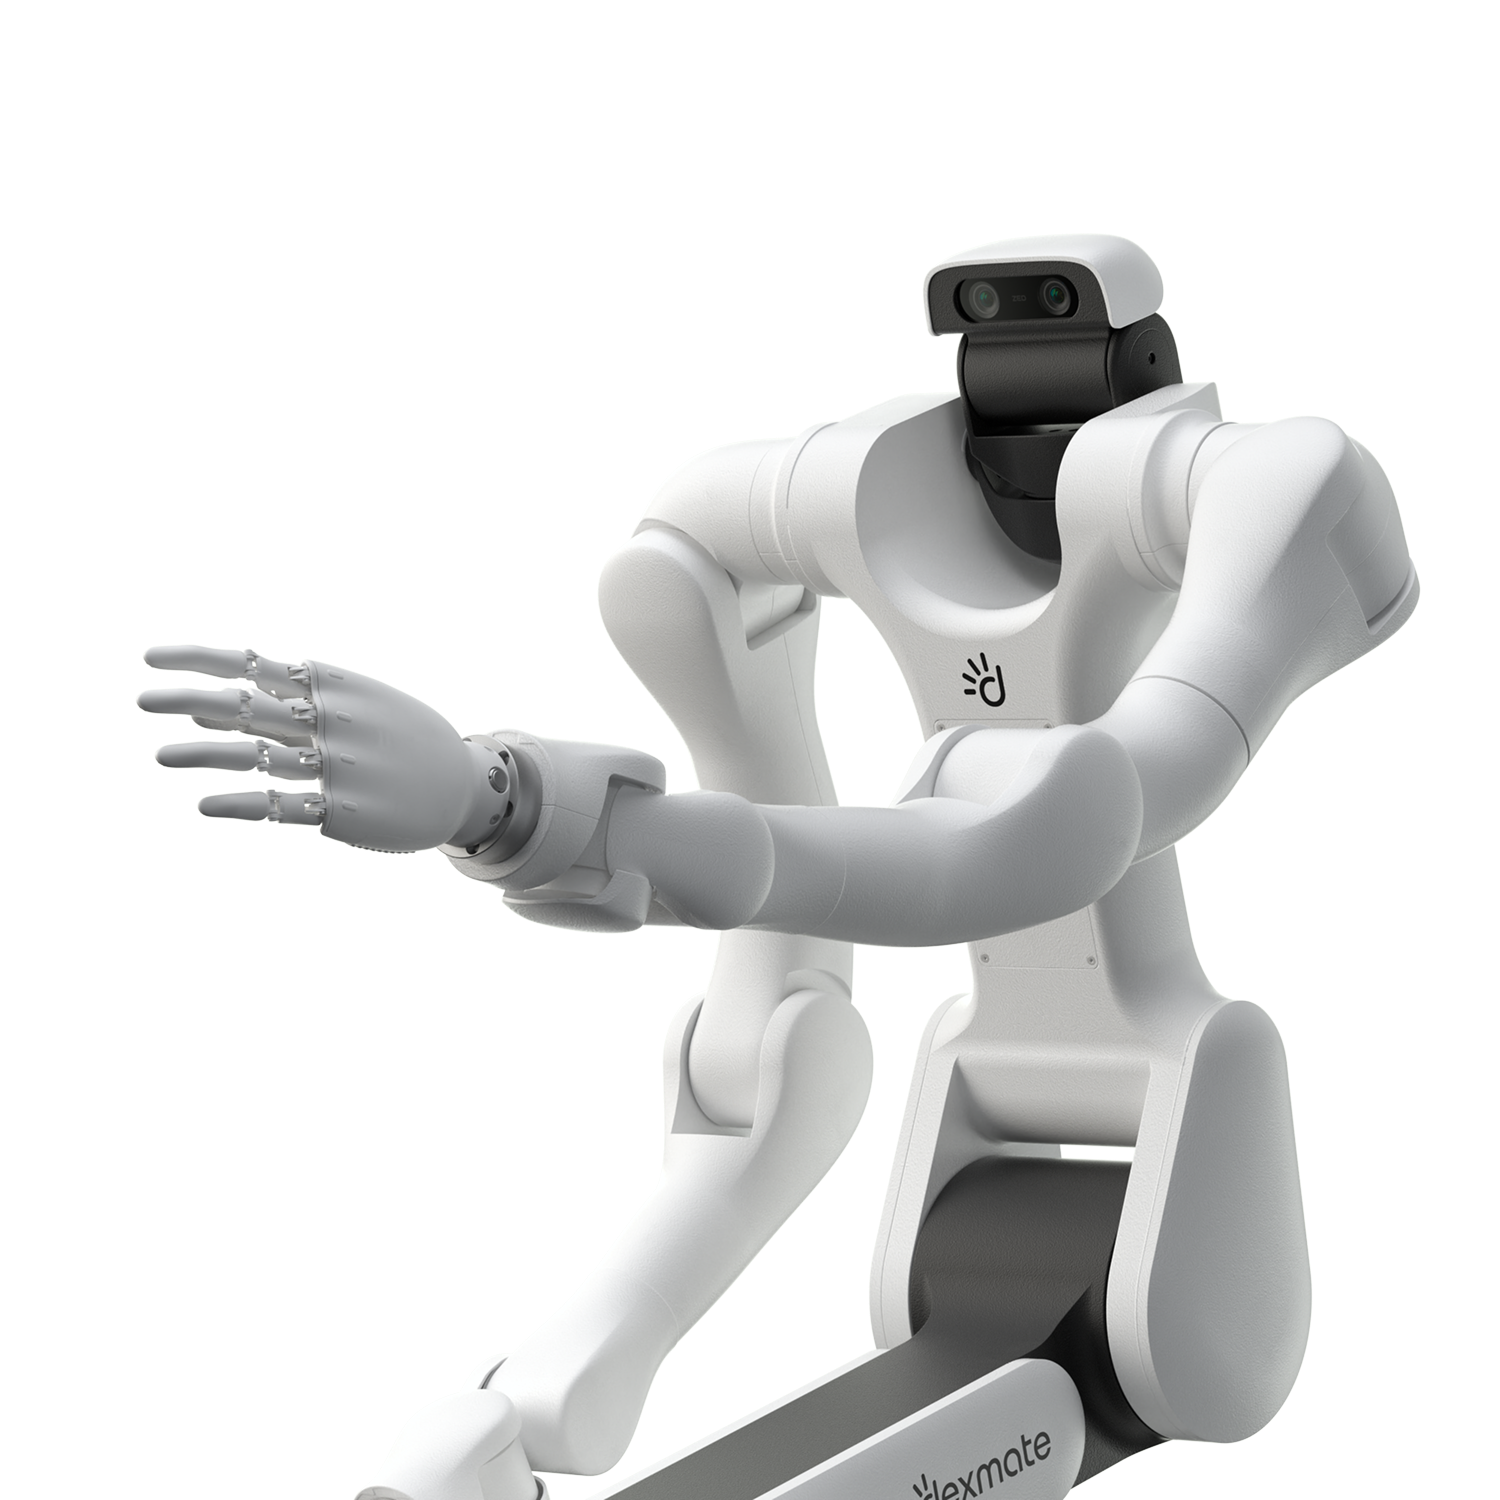
The project describes its robot as a 22-DoF bimanual platform. The released code identifies it as a Dexmate Vega with Sharpa Wave hands and fingertip tactile sensors, which ran all six contact-rich tasks. Vega is available today as Vega 1 Pro and Vega 1 U. See all research published on Dexmate robots.
Related Research
Start Your Physical AI Journey with Us