ResFiT: Residual Off-Policy RL for Fine-Tuning Robot Policies
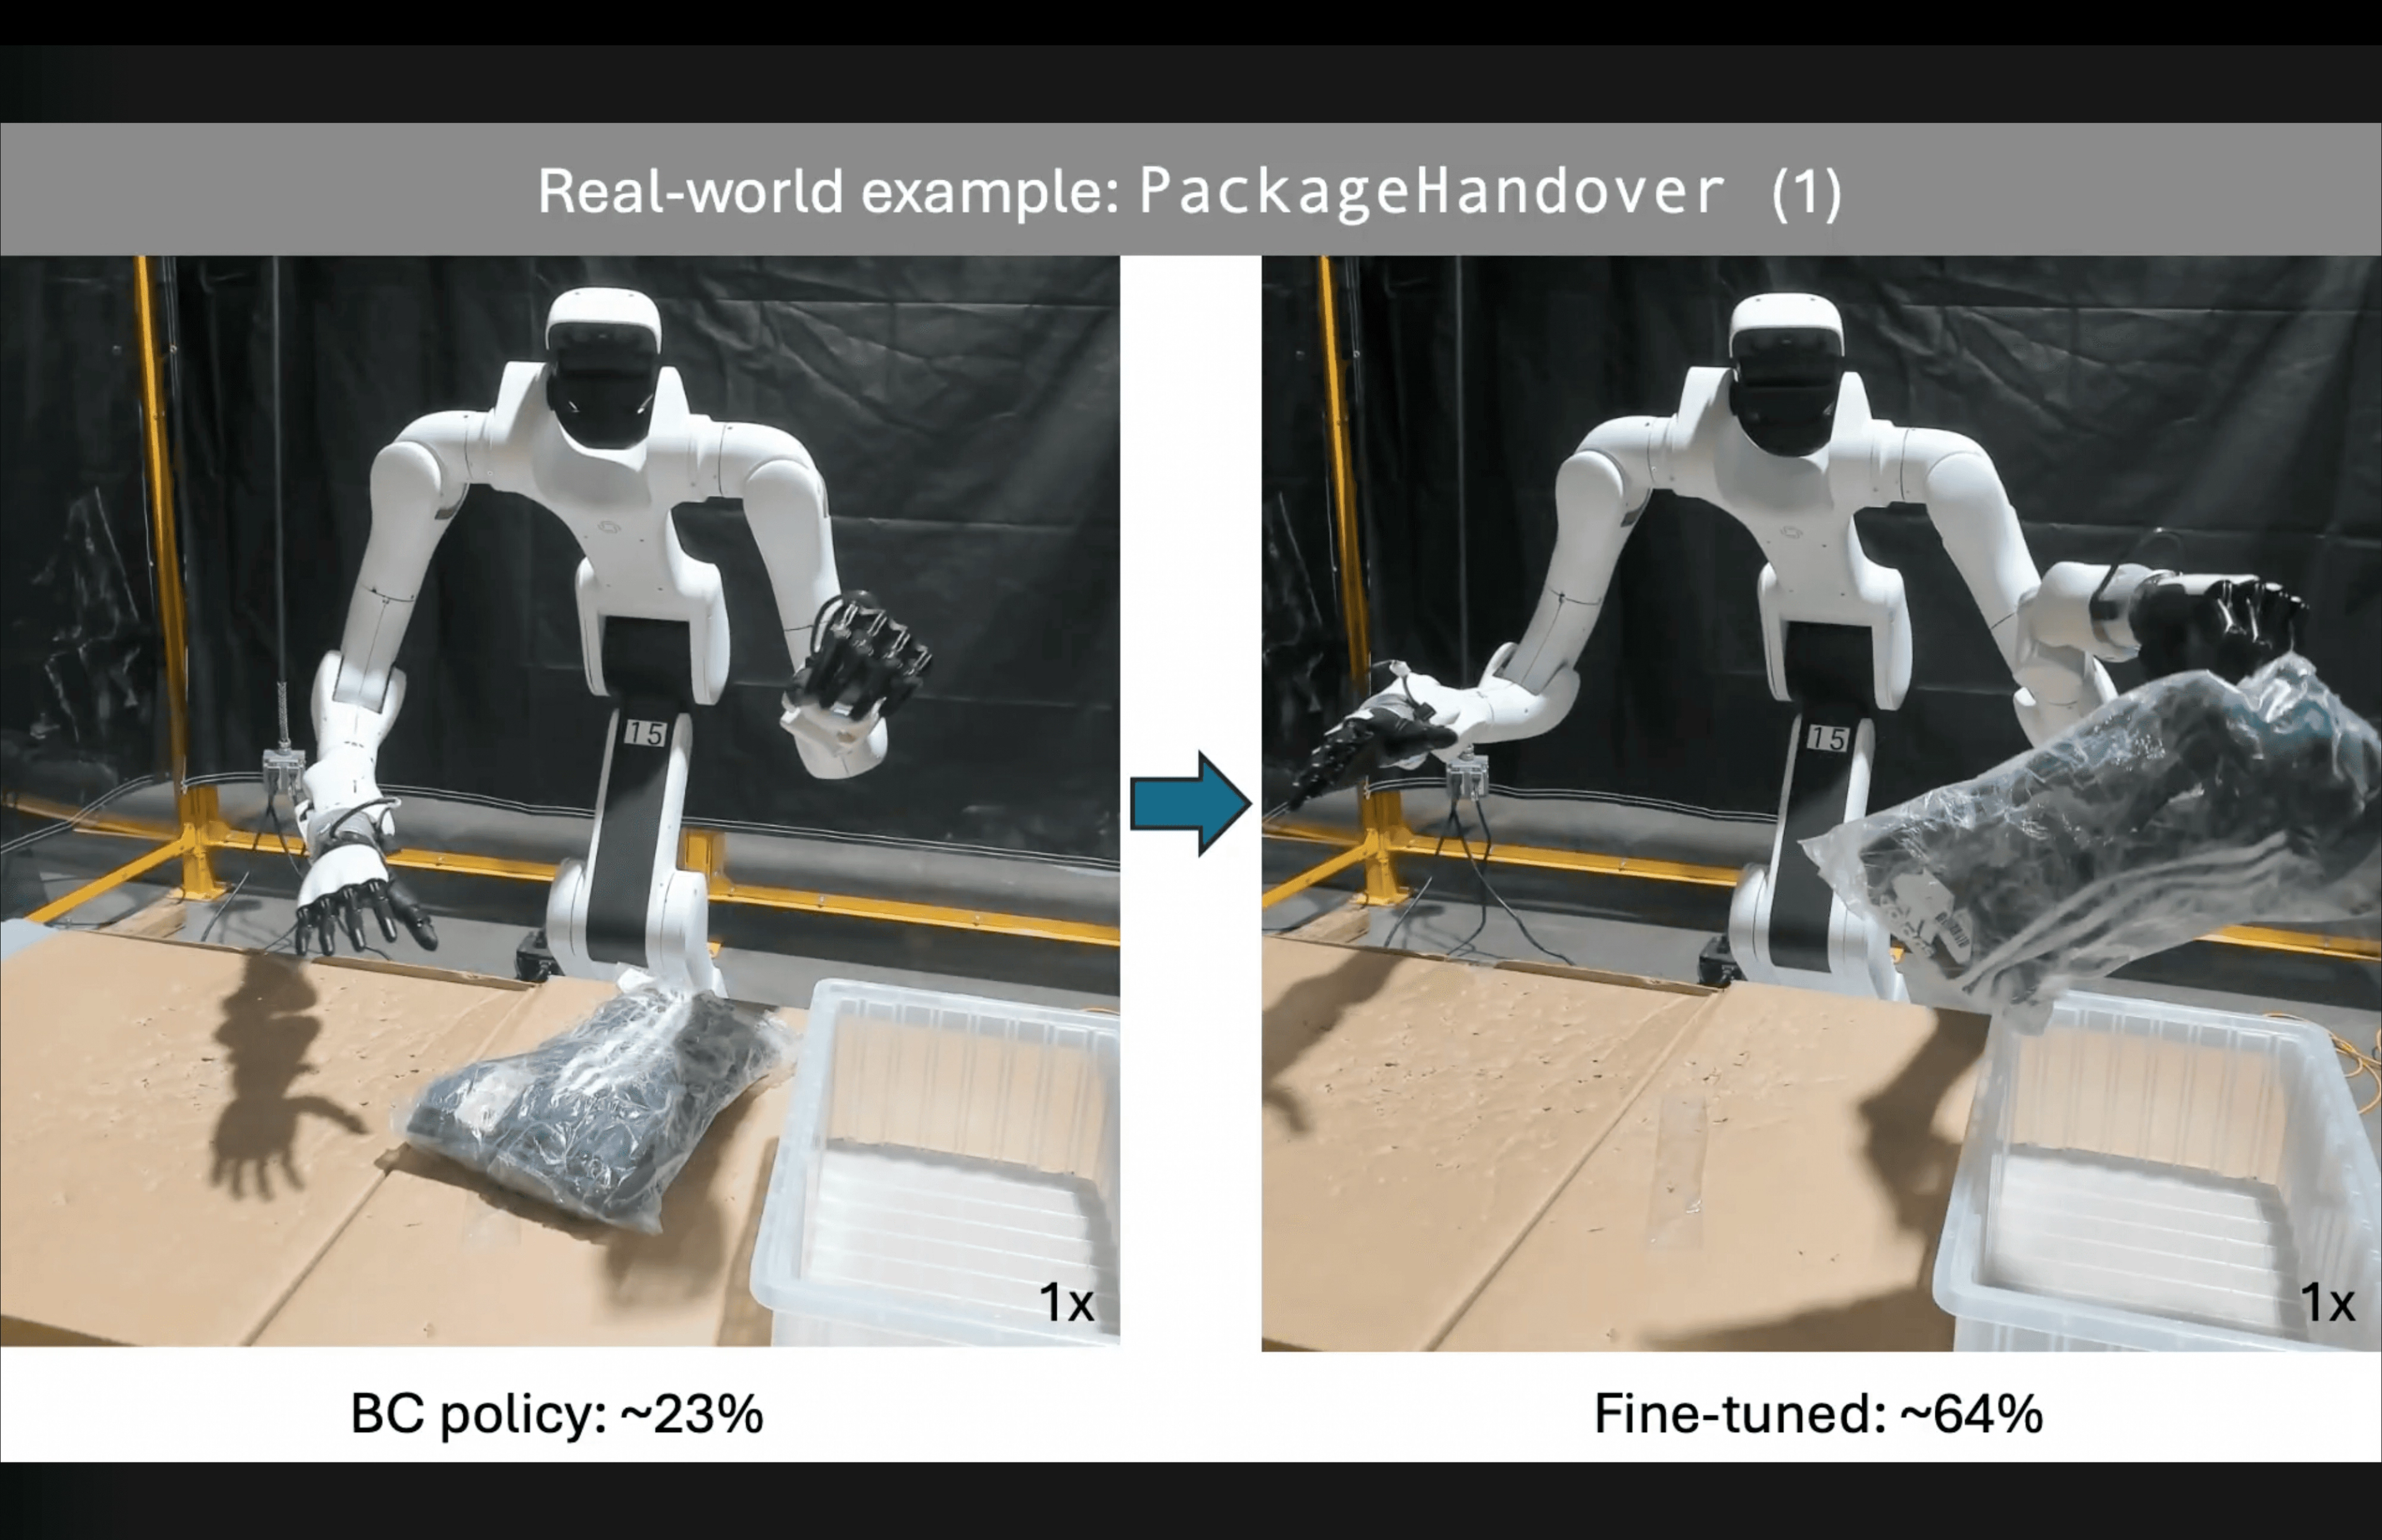
Amazon FAR fine-tunes a behavior cloning policy with a small residual learned by off-policy reinforcement learning. On a Dexmate Vega, package handover success rose from about 23 percent to about 64 percent.
Residual Off-Policy RL for Finetuning Behavior Cloning Policies
- 1Amazon FAR (Frontier AI & Robotics)
- 2Stanford University
- 3Carnegie Mellon University
- 4UC Berkeley
* Work done while interning at Amazon FAR · † Work done while at Amazon FAR
arXiv preprint arXiv:2509.19301
Abstract
Recent advances in behavior cloning (BC) have enabled impressive visuomotor control policies. However, these approaches are limited by the quality of human demonstrations, the manual effort required for data collection, and the diminishing returns from offline data. In comparison, reinforcement learning (RL) trains an agent through autonomous interaction with the environment and has shown remarkable success in various domains. Still, training RL policies directly on real-world robots remains challenging due to sample inefficiency, safety concerns, and the difficulty of learning from sparse rewards for long-horizon tasks, especially for high-degree-of-freedom (DoF) systems. We present a recipe that combines the benefits of BC and RL through a residual learning framework. Our approach leverages BC policies as black-box bases and learns lightweight per-step residual corrections via sample-efficient off-policy RL. We demonstrate that our method requires only sparse binary reward signals and can effectively improve manipulation policies on high-degree-of-freedom (DoF) systems in both simulation and the real world. In particular, we demonstrate, to the best of our knowledge, the first successful real-world RL training on a humanoid robot with dexterous hands. Our results demonstrate state-of-the-art performance in various vision-based tasks, pointing towards a practical pathway for deploying RL in the real world.
Citation
@misc{ankile2025residualoffpolicyrlfinetuning, title = {Residual Off-Policy RL for Finetuning Behavior Cloning Policies}, author = {Lars Ankile and Zhenyu Jiang and Rocky Duan and Guanya Shi and Pieter Abbeel and Anusha Nagabandi}, year = {2025}, eprint = {2509.19301}, archivePrefix = {arXiv}, primaryClass = {cs.RO}, url = {https://arxiv.org/abs/2509.19301},}Platform
The real-world experiments use a Dexmate Vega, described in the work as a wheeled humanoid, fitted with two 6-DoF OyMotion hands. On a package handover task, the behavior cloning policy succeeded about 23 percent of the time and the fine-tuned policy about 64 percent. Vega is available today as Vega 1 Pro and Vega 1 U. See all research published on Dexmate robots.
Related Research
Start Your Physical AI Journey with Us